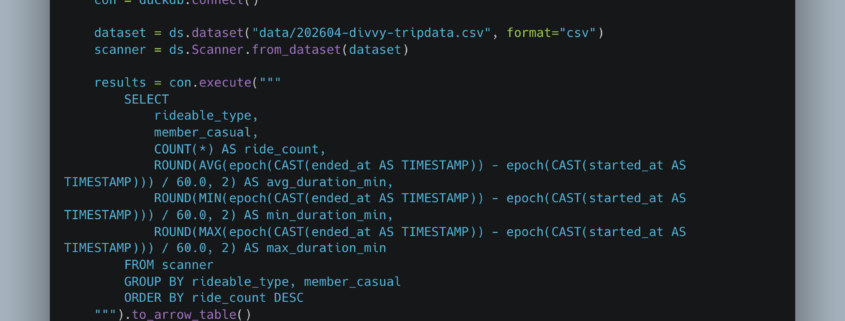
It’s hard to find the bright, shining stars amid the doom and gloom the tech world seems to be floundering in. When the going gets tough, I like to remind myself that there are lots of new and exciting tools released in the last few years, most of which, when combined, have not been part of the great LLM training material, leaving some fun left to explore.

Two of my newest favorite tools, DuckDB and Apache Arrow, have been around a while but are now becoming more integrated, starting to stand more firmly on their own and together.
Read more

Apache Arrow entered the data scene quietly; for years, it languished in obscurity, unheard of and uncared for by the data community. Back in the olden days of 2022, which feels like another world, I was happily using and writing about Arrow as a data processing tool. A lot has changed since then, and Arrow has catapulted its way into everyday data engineering conversations.

Read more

I finally hit that point that every engineer eventually reaches with a tool they once loved, that moment where frustration quietly builds over time and then suddenly flips into a decision, not because of one catastrophic failure but because of the accumulation of too many small ones. That was me with Polars. After years of using it, promoting it, and even putting it into production workloads early on, I reached the point where I removed it entirely from a set of critical pipelines and replaced it with DuckDB without much hesitation.

Before anyone jumps in to defend Polars or call this an overreaction, it is worth understanding that this was not a spur-of-the-moment decision. This was the result of years of real-world usage, repeated friction, and a growing realization that what matters most in a production data platform is not theoretical performance or benchmark wins, but consistency, predictability, and trust that the tool behaves the same way every time it runs.

Read more

I’ve been a Polars bro for most of the last few years. Why? It’s Rust-based, fast, DataFrame-centric, just the way I like it. It also had the excellent feature, right from the start, of Lazy Execution. A few years ago, maybe two, I actually put Polars into production, running on Airflow, working with S3 and reading Delta Lake tables.

I was in love.

Read more

Recently, I had to migrate a few hundred Delta Lake tables that were partitioned over to Liquid Clustering. It seems straightforward on the surface, but everything usually does, until it isn’t. There was no rocket science involved here, but I did want to write this up to help the myriad of others who will probably want/need to move from partitioning to liquid clustering over the next few years.

Databricks recommends liquid clustering for all new Delta Lake tables. Based on past testing, liquid clustering indeed offers significant performance gains.

Again, the difference between a partitioned table and a liquid clustered table, in terms of DDL, is not very much, as you can see.

Read more

Well, all the bottom feeders (Iceberg and DuckDB users) are howling at the moon and dancing around a bonfire at midnight trying to cast their evil spells on the rest of us. Apache Iceberg writes with DuckDB? Better late than never I suppose.

Your witchy ways won’t work on me.

Not going to lie, Iceberg writes with MotherDuck is an interesting concept. MotherDuck is lit and Iceberg only puts a little ice on the fire.

Many other tools like Polars or Daft have been offering Iceberg writes for ages now, it’s about time DuckDB preened its feathers and added write support. Up until now the DuckDB Iceberg Extension has all about the read. But, that is pretty much good for HelloWorld() crap pumped and dumped on Redditors.

We need write support in the real production world. Oh, and not on some Iceberg table stored on your laptop you ninny.

Read more

So, you’re just a regular old Data Engineer crawling along through the data muck, barley keeping your head above the bits and bytes threatening to drown you. At point in time you were full of spit and vinegar and enjoyed understanding and playing with every nuance known to man.

But, not you are old and wizened, exhausted with the never ending stream of JIRA tickets from which you can never get ahead. You write lots of Spark jobs, consider yourself a PySpark pipeline writing expert … but when it comes to Spark performance tuning and optimizations? That’s for the birds.

Well my friend, don’t let all the Scala experts look down on you, scare you into thinking Spark performance is simply to complex for the common developer. Liars, every last mother one of them.

Read more