Ok, not going to lie, I rarely find anything of value in the dregs of r/dataengineering, mostly I fear, because it’s %90 freshers with little to no experience. These green behind the ear know-it-all engineers who’ve never written a line of Perl, SSH’d into a server, and have no idea what a LAMP stack is. Weak. Sad.

We used to program our way to glory, up hill both ways in the snow. All you do is script kiddy some Python code through Cursor.

A recent post on Data Modeling, specifically that data modeling is dead, caught my eye. A rare piece of gold mixed in the usual pile of crap. It some truth being spoken on the interwebs, hold onto your panties you bright eyed data zealot. I agree %100 with this sentiment.

DATA MODELING IS DEAD.
Read more

Did you know that Polars, that Rust based DataFrame tool that is one the fastest tools on the market today, just got faster?? There is now GPU execution on available on Polars that makes it 70% faster than before!!

Read more

You know, after literally multiple decades in the data space, writing code and SQL, at some point along that arduous journey, one might think this problem would be solved by me, or the tooling … yet alas, not to be.

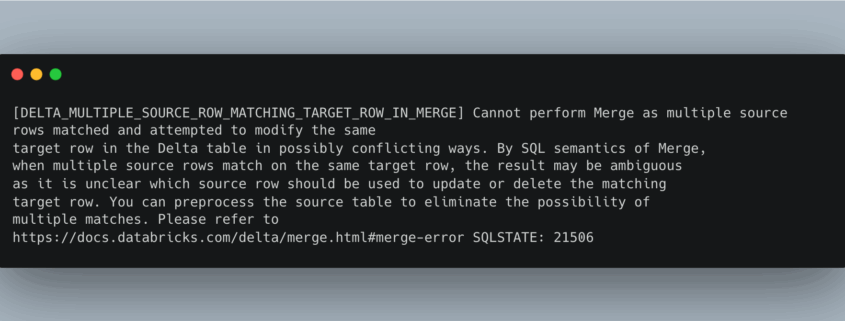
Regardless of the industry or tools used, such as Pandas, Spark, or Postgres, duplicates are a common issue in pipelines, and SQL remains the most classic and iconic problem. Things just never change, and humans never learn their lessons, at least I don’t.

Read more

Deletion Vectors are a soft‑delete mechanism in Delta Lake that enables Merge‑on‑Read (MoR) behavior, letting update/delete/merge operations mark row positions as removed without rewriting the underlying Parquet files. This contrasts with the older Copy‑on‑Write (CoW) model, where even a single deleted record triggers rewriting of entire files YouTube+8docs.delta.io+8Medium+8.

Supported since Delta Lake 2.3 (read-only), full deletion vector support for DELETE/UPDATE/MERGE appeared in later versions: DELETE in 2.4, UPDATE/MERGE in Delta 3.x Miles Cole+4docs.delta.io+4delta.io+4.


✅ Why Use Deletion Vectors?

  • Faster small changes: Only binary bitmap metadata is written, rather than rewriting large Parquet files.

  • Write efficiency: Particularly efficient when changes affect sparse rows across many files Medium+11delta.io+11Towards AI+11.

  • ACID semantics preserved: Readers still get the correct view by merging with DLV metadata at read time.

However:

  • Read-time overhead: Filtering DLV metadata adds overhead during queries.

  • Maintenance needed: Unapplied deletion markers build up until compaction or purge Medium+6japila-books+6Towards AI+6.

Read more

So … Astronomer.io … who are they and what do they do?

It’s funny how, every once in a while, the Data Engineering world gets dragged into the light of the real world … usually for bad things … and then gets shoved under the carpet again. Recently, because of the transgressions of the CEO of Astronomer, a little side fling at a Coldplay concert that went viral, Astronomer has popped into the spotlight.

I’ve been around Astronomer for a long time, so I will give you the lowdown on who they are, and how they become a billion, yes Billion, dollar company that you’ve never heard of.

Read more

Running dbt on Databricks has never been easier. The integration between dbtcore and Databricks could not be more simple to set up and run. Wondering how to approach running dbt models on Databricks with SparkSQL? Watch the tutorial below.

There are things in life that are satisfying—like a clean DAG run, a freshly brewed cup of coffee, or finally deleting 400 lines of YAML. Then there are things that make you question your life choices. Enter: setting up Apache Polaris (incubating) as an Apache Iceberg REST catalog.

Let’s get one thing out of the way—I didn’t want to do this.

Read more

The blog post reviews an Apache Incubating project called Apache XTable, which aims to provide cross-format interoperability among Delta Lake, Apache Hudi, and Apache Iceberg. Below is a concise breakdown from some time I spend playing around this this new tool and some technical observations:

Read more

Maybe I’m the only one who thinks about it, not sure. The Lake House has become the new Data Warehouse, yet when I ask this question “What makes a health Lake House?” no one is sure what the answer is, or you get different answers.

It seems like a pretty important question considering that Lake Houses have taken the data landscape by storm and now store the vast majority of our data. With all the vendors pumping out Lake House formats and platforms (think Delta Lake and Apache Iceberg), the main focus seems to be adding features and addressing internal data quality, aka the quality of the data stored in the Lake House itself.

Read more

When it comes to building modern Lake House architecture, we often get stuck in the past, doing the same old things time after time. We are human; we are lemmings; it’s just the trap we fall into. Usually, that pit we fall into is called Spark. Now, don’t get me wrong; I love Spark. We couldn’t have what we have today in terms of Data Platforms if it wasn’t for Apache Spark.

Read more